The correct approach is a layered, risk-calibrated program that treats prompts as governed artifacts, not throwaway text. That means disciplined prompt design, verification effort matched to consequence, and an enforceable control plane behind every deployment. Anchor it to FDA lifecycle guidance, the NIST AI Risk Management Framework, and the PLOS verification model, and you have a program that auditors, regulators, and your own scientists can trust.
TL;DR:
- Effective prompt governance requires assigning ownership and maintaining detailed documentation at each lifecycle stage, including intent, approval, and retirement.
- Designing prompts with clear context, task, constraints, and output format significantly reduces failure risk before verification begins.
- Verification efforts should be calibrated to output risk, with red-band prompts demanding full traceability, dual review, and strict audit trails, while green-band outputs require minimal oversight.
- Leveraging a controlled architecture with separate control and workflow planes ensures policy enforcement without hampering scientific work or increasing error risk.
- Vendors must provide audit logs, change notices, validation evidence, and data residency guarantees, with continuous monitoring to detect drift or unexpected behavior in prompts.
Table of Contents
- Building a Prompt Governance Framework for Life Sciences
- How Should You Design Prompts for Regulated Scientific Work?
- Matching Verification Effort to Output Risk
- Designing a Control Plane and Workflow Plane for Prompt Execution
- Vendor and Platform Risk: What to Demand from AI Suppliers
- A 90-Day Path to Standing Up Prompt Governance
- What Do FDA, NIST, and OECD Guidance Mean for Prompt Controls?
- How an Operational Partner Implements This in Practice
- Training Programs That Actually Change Behavior
- When a Prompt Fails: Incident Response and Remediation
- Protecting Data in Prompt Inputs and Outputs
- Measuring Whether Your Governance Program Actually Works
- Where the Real Gap Sits in Prompt Governance
- Get Governed Prompt Programs Running Without the Guesswork
- Sources
- FAQ
Building a Prompt Governance Framework for Life Sciences
Prompt governance in life sciences only works when someone owns each stage of a prompt's life, from first draft to retirement. Treat prompts the way you'd treat a validated method or an SOP: versioned, attributable, and subject to change control. That single shift, from "prompt as scratch note" to "prompt as regulated asset," is what separates a governance program that survives an audit from one that collapses under the first inspection.
The lifecycle has six stages, and each needs a named owner, not a committee.
- Assess. A workflow owner and a risk lead classify the intended use case, the data it touches, and the downstream consequence if the output is wrong.
- Design. A subject-matter expert and a prompt engineer draft the prompt using the four-component template (covered below) and record the intent statement.
- Approve. A designated approver, typically a regulatory or quality lead for high-risk uses, signs off before the prompt touches a live workflow.
- Deploy. IT or platform operations pushes the approved, versioned prompt into the production environment with logging enabled.
- Monitor. A compliance or QA function tracks drift, output quality, and incident flags on a defined cadence.
- Retire. Prompts get sunset when the underlying model, regulation, or use case changes, with the retirement documented as carefully as the launch.
Escalation paths matter as much as the stages themselves. A prompt generating internal literature summaries can probably be approved by a team lead. A prompt drafting language for a regulatory submission or influencing a clinical decision needs sign-off from someone with actual authority over that output category, often a regulatory affairs director or a designated quality officer. Build that escalation ladder before you need it, not after an incident forces the question.
Documentation is the part teams skip and then regret. At minimum, each stage needs: an intent statement describing what the prompt is for and what it must never do, a unique version ID tied to a changelog, the approved use case boundaries, and a record of who signed off and when. Without that paper trail, you cannot answer the basic audit question: "Who approved this prompt, and for what?" NIST's AI risk-management guidance treats documentation and accountability as core controls, not optional add-ons, and life-sciences compliance leaders should read it the same way.
How Should You Design Prompts for Regulated Scientific Work?
Good prompt design is the cheapest risk control you have. Get the prompt right and you shrink the failure modes before verification even starts, which is exactly the logic behind the PLOS Computational Biology risk framework for large language model use in life-science research. A sloppy prompt forces your verification team to catch problems that never needed to exist.
Structure every prompt around four components:
- Context. State exactly what domain, dataset, or document set the model should draw on. "Using only the attached clinical study report and the ICH E3 template" is a context statement. "Help me write a report" is not.
- Task specification. Name the precise deliverable: "Draft the safety summary section," not "summarize the safety data." Vague task language produces vague, unverifiable output.
- Constraints. Set hard boundaries: required citations, banned inferences, tone, length, and what the model must flag rather than answer (for example, any claim not directly supported by the supplied source).
- Output format. Specify structure down to headers, tables, or the exact fields a downstream system expects, so the output slots into your workflow without manual reformatting.
A prompt asking a model to summarize adverse event narratives for a periodic safety update report should explicitly restrict it to the supplied case narratives, forbid it from inferring causality, and require it to flag any narrative lacking a coded MedDRA term. That single constraint, "use only supplied sources," does more risk-reduction work than an entire downstream review cycle.
Provenance enforcement follows the same logic. Tell the model what it may not do as clearly as what it may do: no external knowledge, no unsupported extrapolation, no filling gaps with plausible-sounding text. Bounded action spaces, where the model can only select from pre-approved sources or tools, cut hallucination risk far more reliably than after-the-fact fact-checking.
Version every prompt artifact with a stable naming convention: workflow name, version number, approval date, and the SOP or dataset it links to. Store the full bundle, context, task spec, constraints, and output format, as a single immutable record. One useful pattern from the PLOS framework is hashing that bundle so any output in your system logs can be traced back to the exact prompt version that produced it, an approach worth adopting even outside academic research settings.
Pro Tip: Name prompt versions the way you'd name a controlled document, not a file on your desktop. "PSUR_summary_v3_2026-02-10_approved" tells an auditor everything "final_final_v2" never will.
Matching Verification Effort to Output Risk
Not every AI output deserves the same scrutiny, and treating them all identically wastes the resources that actually matter for the outputs that could hurt someone. The PLOS risk framework proposes calibrating verification intensity to three dimensions: verifiability (how easily can a human check the output against ground truth), required expertise (how specialized is the reviewer needed), and consequence (what happens if the output is wrong).
Map every prompt-generated output to a band before it enters a workflow:
- Green band: high verifiability, low consequence. Internal literature scans, brainstorming lists, first-pass draft outlines. Spot-check review is sufficient.
- Amber band: moderate verifiability or moderate consequence. Draft regulatory text, code that touches non-critical analysis pipelines, internal training material. Requires a qualified reviewer sign-off and a documented check against source material.
- Red band: low verifiability, high consequence, or both. Language destined for a regulatory submission, clinical protocol text, code feeding a validated analytical system. Requires dual review, full traceability to source, and a named accountable approver.
A prompt generating a literature synthesis for internal hypothesis generation sits comfortably in green, because a scientist can rapidly cross-check citations. The same model drafting clinical trial protocol language sits in red: getting the eligibility criteria phrasing wrong could alter patient enrollment. Code generated to automate a regulatory filing template needs expert review even if it looks syntactically correct, because a subtle logic error might not surface until submission.
Documentation obligations scale with the band. Green-band outputs need a basic log: prompt version, date, output hash. Amber-band outputs need the reviewer's name, the specific claims checked, and a retention period matching your quality system's standard document retention. Red-band outputs need full audit trails: reviewer credentials, specific source-to-output traceability, sign-off timestamps, and retention aligned with your longest regulatory record-keeping requirement, often the life of the product plus a defined number of years.
This is the single most common governance failure life-sciences teams make: applying red-band scrutiny to everything, which burns reviewer time and breeds workarounds, or applying green-band scrutiny to everything, which is how ungrounded text ends up in a submission. Calibration, not uniform caution, is the actual control.
Designing a Control Plane and Workflow Plane for Prompt Execution
A workable operational architecture separates governance enforcement from task execution. That split, often called a control plane and a workflow plane, gives you a place to enforce policy without slowing down the scientific work itself. A dual-layer architecture described in the Mozi research on governed autonomy for drug discovery agents illustrates the pattern clearly, even though it was built for a research context rather than a commercial platform.
The Control Plane handles policy, not tasks. It enforces role-based access control so only approved roles can invoke red-band prompts, maintains immutable audit logs of every prompt invocation and output, and applies hard tool-filtering so a given worker process can only call the specific tools or data sources its role permits. No component in this layer touches scientific content directly. It exists purely to say yes, no, or "escalate to a human."
The Workflow Plane does the actual work: stateful skill graphs that mirror your SOPs, executing multistep scientific tasks such as literature triage, data extraction, or draft generation, while reporting every action back to the control plane for logging.
That supervisor-worker pattern matters because it prevents the failure mode where a single unconstrained agent drifts across tasks it was never authorized to perform. Mozi's design uses strict per-worker tool lists and distinct execution modes, strict versus permissive, so a production run cannot suddenly access a tool nobody approved for that workflow. Human-in-the-loop gates get inserted at exactly the transition points where risk climbs: before a red-band output leaves the workflow plane, before any action touches a live regulatory or clinical system, and whenever the model's confidence signal or output pattern deviates from its established baseline.
Integration points deserve deliberate design rather than default settings. Where prompt-driven workflows touch an electronic lab notebook, the control plane should log every read and write with the same rigor it applies to the prompt itself. Where they touch a LIMS, tool-filtering should restrict write access to specific, pre-approved fields. Where they feed a regulatory authoring system, the HITL gate belongs immediately before content crosses into that system, never after.
- Control Plane: RBAC, audit logging, hard tool-filtering, policy enforcement.
- Workflow Plane: stateful skill graphs, SOP-mirrored task execution, status reporting.
- HITL gates: placed at red-band transitions and system-of-record boundaries.
- Integration discipline: ELNs, LIMS, and regulatory authoring systems each get their own access scope, not a shared credential.
Vendor and Platform Risk: What to Demand from AI Suppliers
Most life-sciences teams don't build their own models. They embed prompts inside a vendor platform, which means governance has to extend into procurement and contract language, not just internal process. If your vendor changes an underlying model without telling you, your validated prompt behavior can shift overnight with zero internal signal, highlighting the importance of understanding the role of AI in healthcare for effective integration and change management.
Before signing, or before renewing, run the platform through a short but non-negotiable checklist:
- Does the vendor provide audit logs covering every prompt invocation, not just aggregate usage statistics?
- What is the contractual notice window before a model or prompt-handling update, and is it long enough for you to revalidate?
- Can the vendor demonstrate data residency guarantees consistent with your regulatory obligations?
- What provenance evidence exists showing how the platform's outputs trace back to source data?
- Has the vendor supplied validation evidence, not marketing claims, for the specific use case you're deploying?
Contract language should lock in change-notice periods measured in weeks, not "at our discretion." Push for rollback rights so you can revert to a prior model or prompt-handling version if an update breaks a validated workflow. Insist on audit access, meaning your compliance team can pull logs on demand, not just on the vendor's reporting schedule. And require validation evidence delivered proactively whenever the vendor materially changes anything upstream of your prompts.
Once the contract is signed, monitoring doesn't stop. Set up continuous monitoring on vendor-hosted prompts the same way you would for an internal one, watching output drift, error rates, and unannounced behavior shifts, with alerting thresholds tied to your risk bands. A platform review, described in more depth in HaiPhai's look at AI governance platforms for biotech teams, belongs on the same cadence as your internal audit schedule, not as an afterthought triggered only by an incident.
A 90-Day Path to Standing Up Prompt Governance
You don't need a year-long transformation program to get a defensible governance baseline in place. A focused 90-day push, followed by a scaling phase, gets most teams from ad hoc prompt use to an auditable program.
- Weeks 1 to 3: Inventory. Catalog every prompt currently in active use across regulatory, clinical, and scientific workflows, no matter how informal. You cannot govern what you haven't counted.
- Weeks 3 to 5: Risk classification. Assign each inventoried prompt to a green, amber, or red band using the verifiability, expertise, and consequence criteria.
- Weeks 5 to 8: Template rollout. Apply the four-component prompt structure to two or three of your highest-value workflows first, not all of them at once. Prove the model on a small set before scaling.
- Weeks 8 to 10: Ownership assignment. Name a stage owner and an approver for each workflow in scope, with documented escalation paths.
- Weeks 10 to 13: Monitoring configuration. Stand up logging and alerting for the in-scope workflows, calibrated to each output's risk band.
Track a small set of KPIs from day one: prompt coverage (the percentage of active workflows using a versioned, approved prompt), time to approval (how long a new prompt takes from draft to sign-off), incidents prevented or caught (flagged outputs stopped before reaching a downstream system), and verification throughput (how many outputs your reviewers can process per week without becoming the bottleneck).
Change management determines whether any of this survives contact with a busy clinical operations team. Run short training sessions tied to actual workflows, not generic AI-literacy decks. Establish a governance review board that meets on a fixed cadence, monthly is usually enough at this stage, to review incident flags and approve new prompt templates. Communicate changes to stakeholders before they hit production, not after someone notices their prompt suddenly requires an extra sign-off.
What Do FDA, NIST, and OECD Guidance Mean for Prompt Controls?
Regulatory signals on AI governance are converging on the same core expectation: documented, auditable, change-controlled systems. The FDA's guidance on AI/ML-enabled device software functions describes predetermined change control plans, meaning manufacturers must specify in advance how a model or algorithm may change and how those changes get validated. Prompts that materially affect a regulated output belong inside that same change-control scope, versioned and validated on the same schedule as the model itself.
NIST's AI Risk Management Framework translates that expectation into operational controls your compliance team can actually implement: documented risk assessments, accountability assignments, and auditability requirements that map directly onto the lifecycle stages and verification bands described earlier in this piece.
International signals reinforce the same direction. OECD AI principles call for documentation, oversight, and governance proportional to risk, echoing the calibrated verification approach rather than a one-size-fits-all review standard. Executive-level policy in the United States, including White House actions on AI leadership, has raised the bar for what auditable, accountable governance looks like at the enterprise level, which increases the scrutiny vendors and internal programs alike should expect going forward.
- FDA: change-control plans extend to prompt versioning for regulated outputs.
- NIST: documentation and auditability controls map to lifecycle and verification stages.
- OECD: proportional, risk-based oversight rather than uniform review.
- Executive policy: rising expectations for enterprise-level auditability and vendor accountability.
How an Operational Partner Implements This in Practice
A framework on paper doesn't govern anything until it's wired into how your teams actually work. An operating partnership model exists to translate a governance framework into daily practice within regulatory, clinical, and scientific operations, rather than leaving it unused in documentation.
A diagnostic process can map existing prompt use, workflow bottlenecks, and risk exposure before redesign begins, functioning as an assessment stage of the lifecycle, typically performed by embedded experts rather than generic software alone. Governed automation can then be developed around a client's specific regulatory and scientific context, rather than applying a generic template.
This is where client-specific proof points belong: named case studies showing time-to-approval improvements, testimonials from regulatory or clinical operations leaders who've run the diagnostic, and metrics such as prompt coverage percentage, incidents caught pre-submission, or hours reclaimed per regulatory cycle. Author credentials and bios for contributing subject-matter experts also fit naturally in this section once available.
Training Programs That Actually Change Behavior
Governance policies fail quietly when the people writing prompts every day never learned the rules. Training has to target three distinct groups, because a single generic session teaches nobody the specific thing they need.
Scientists and clinical operations staff writing prompts day-to-day need hands-on instruction in the four-component template and the risk bands, ideally using their own real workflows as training examples rather than abstract cases. A regulatory writer drafting submission language needs to internalize why "use only supplied sources" isn't a suggestion; it's the constraint that keeps unsupported claims out of a filing.
Approvers and reviewers need a different curriculum entirely: how to evaluate whether a prompt's constraints actually match its risk band, and how to spot when a red-band output has been miscategorized as amber to skip a review step. This is a judgment skill, not a checklist skill, and it needs periodic refreshers as new use cases emerge.
Executives and governance board members need the shortest but highest-leverage training: understanding what the KPIs mean, what an escalation actually signals, and when to intervene rather than defer entirely to the technical team. A board member who can't interpret a rising incident-flag rate can't govern anything.
Run refresher sessions tied to actual incidents or near-misses rather than a fixed annual calendar. A single well-analyzed near-miss, walked through with the team that experienced it, teaches more than a slide deck ever will. Tie training completion to system access: no approved prompt authorship without the current training cycle logged.
When a Prompt Fails: Incident Response and Remediation
Prompt-related failures range from a hallucinated citation in an internal summary to language that made it partway into a regulatory draft before someone caught it. Your incident response plan needs to scale to that range, not treat every flag as a five-alarm event or, worse, treat a serious one as routine.
The first step is detection, which only works if your monitoring is already tuned to each risk band. A green-band error might surface through a routine spot-check. A red-band error should trigger an automatic alert the moment output deviates from expected patterns or fails a provenance check.
Once flagged, contain the blast radius immediately: freeze the specific prompt version, not the entire workflow, so unaffected use cases keep running while you investigate. Trace the failure back through your version-controlled prompt bundle, the same immutable artifact discussed earlier, to determine whether the fault sits in the prompt design, the underlying model, the source data, or a reviewer who missed a required check.
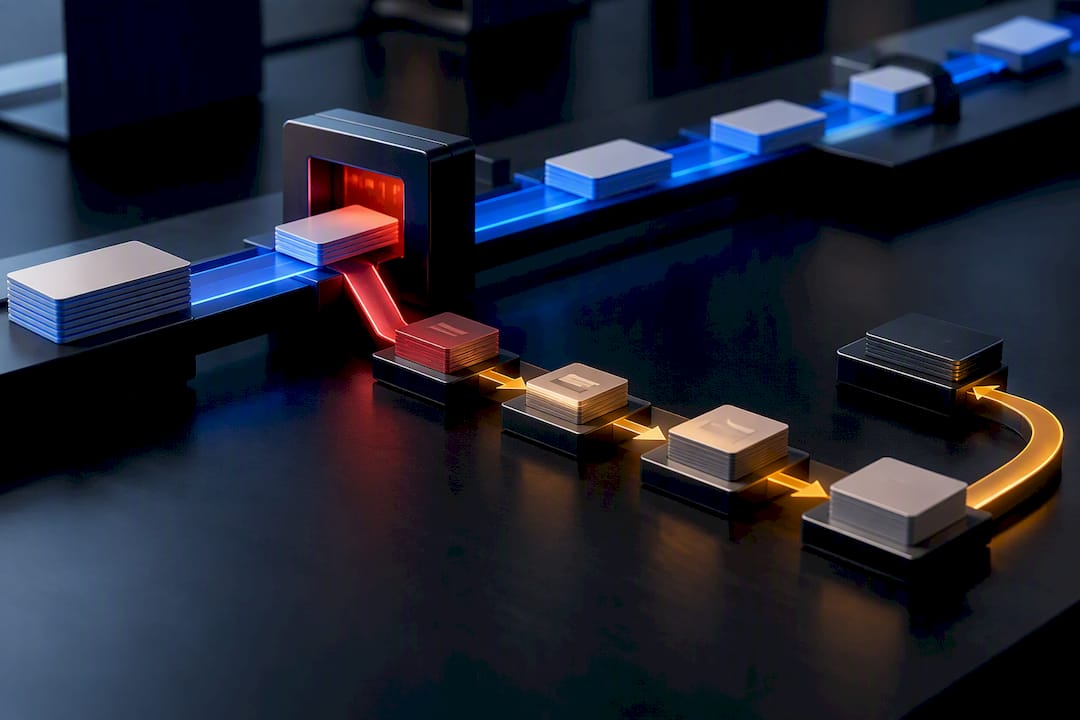
Remediation has two tracks that must both close out: fixing the immediate output (correcting or retracting anything downstream that relied on the flawed result) and fixing the systemic gap (revising the prompt, tightening a constraint, or retraining a reviewer). Document both tracks separately, because an auditor will ask what changed in the prompt and what changed in the process.
Every incident, regardless of severity, feeds back into your governance review board's agenda. A pattern of amber-band near-misses is often the earliest warning that a verification band was set too loosely, long before a red-band incident forces the issue.
Protecting Data in Prompt Inputs and Outputs
Every prompt you write is a data-handling event, often an under-appreciated one. The context you feed a model, patient-level data excerpts, unpublished study results, proprietary molecule structures, carries the same sensitivity as the source document it came from, and needs the same protection.
Start with input discipline: strip or mask identifiers before they enter a prompt whenever the task doesn't genuinely require them. A literature-summarization prompt rarely needs patient-level identifiers; a prompt drafting a case narrative for a safety report might, and that distinction should be enforced by policy, not left to whoever is typing.
Data residency and retention need explicit answers before a prompt goes into production, especially for platforms hosted outside your own infrastructure: where does the input data live during processing, how long does the vendor retain it, and does that retention period conflict with your own data governance policy. These questions belong on the vendor checklist covered earlier, but they apply equally to internally hosted prompts.
Output handling deserves its own scrutiny. A model output containing an unredacted excerpt of proprietary data, even accidentally, needs the same access controls as the source material it echoes. Log access to red-band outputs the same way you'd log access to the underlying regulated document, because functionally, that's what it has become.
Encryption in transit and at rest, role-based access to prompt logs, and a defined retention schedule matching your quality system's document standards round out the baseline. None of this is exotic. It's the same data governance discipline life-sciences teams already apply to lab data, extended to a new category of asset.
Measuring Whether Your Governance Program Actually Works
A governance program you can't measure is a governance program you're guessing about. The KPIs introduced in the implementation playbook need a permanent home on a recurring dashboard, not a one-time rollout metric.
Prompt coverage tracks the percentage of active AI-assisted workflows running on a versioned, approved prompt rather than an ungoverned one. This is your leading indicator of exposure: low coverage means most of your organization's AI use is happening outside the framework entirely.
Time to approval measures how long a new or revised prompt takes from draft to sign-off. If this number climbs, your review process has become a bottleneck people will start routing around, which defeats the entire program.
Incidents prevented or caught counts flagged outputs stopped before they reached a downstream system, broken out by risk band. A red-band catch is a program working exactly as designed; a red-band miss is the metric that should trigger an immediate review-board session.
Verification throughput tracks how many outputs your reviewers can process per week without becoming the constraint on the whole workflow. If verification throughput can't keep pace with prompt volume, either your verification levels are miscalibrated or you need more qualified reviewers, and that gap should show up in the data before it shows up in a missed deadline.
Report these quarterly to the governance board at minimum, and monthly for any workflow classified red-band. A metric nobody reviews is not a metric. It's decoration.
Where the Real Gap Sits in Prompt Governance
Most published advice on this topic treats prompt governance as a documentation exercise: write a policy, log some versions, call it done. That misses the actual failure point, which is almost always at the handoff between design and verification. Teams write disciplined prompts, then apply the same shallow review to everything downstream regardless of consequence, because building a genuinely tiered verification process is harder than writing a policy PDF.
The frameworks that hold up under real audit pressure, PLOS's risk-calibrated verification model paired with NIST's accountability controls, work precisely because they refuse to treat all AI output as equally risky. That refusal is uncomfortable for compliance teams used to uniform checklists, but it's the only approach that scales without either paralyzing scientists or letting ungrounded text slip into a submission.
If you take one thing from this piece, prioritize the control plane before the prompt library. A beautifully designed prompt with no enforceable audit trail behind it is a liability waiting for an inspector to find it.
— John
Get Governed Prompt Programs Running Without the Guesswork
Building the framework above internally usually means pulling scientists and regulatory staff off their actual work for months to design templates, verification matrices, and audit logging from scratch. A specialized team can manage the build: performing diagnostics to map current prompt exposure and workflow bottlenecks in a matter of weeks rather than quarters, followed by designing governed automation tailored to specific regulatory and clinical contexts.
That's the core difference from a software rollout: HaiPhai's operating partnership puts senior experts inside your operations to build and own the governance layer alongside your team, rather than handing you a template and a login. Depending on where your workflows sit, that can mean regulatory drafting, clinical site activation, or executive-level oversight, all covered under the solutions built for clinical, scientific, and regulatory operations. If your prompt governance program is still living in scattered documents and informal habits, start with the diagnostic and get a concrete map of where you stand before your next audit does it for you.
Sources
- A practical risk framework for large language model use in life science research | PLOS Computational Biology
- NIST AI Risk Management Framework
- Artificial Intelligence and Machine Learning (AI/ML)-Enabled Device Software Functions: Predetermined Change Control Plans
- Mozi: Governed autonomy for drug discovery LLM agents (arXiv)
- Removing barriers to American leadership in artificial intelligence | The White House
FAQ
What Is Prompt Governance in Life Sciences?
Prompt governance is the set of roles, policies, and technical controls that make AI prompt use auditable, versioned, and matched to output risk. It draws on frameworks like the PLOS verification model and NIST's risk-management controls to keep AI-assisted outputs defensible under regulatory review.
How Do You Version Control AI Prompts?
Store each prompt as an immutable bundle of context, task specification, constraints, and output format, tagged with a unique version ID and changelog. Linking that bundle to the SOP and dataset it serves, and hashing it for traceability, lets an audit tie any output back to the exact prompt that produced it.
What Verification Level Does a Regulatory Draft Need?
Text destined for a regulatory submission belongs in the red band: dual review, full traceability to source documents, and a named accountable approver. That's a higher bar than an internal literature summary, which typically needs only spot-check review under the risk-calibrated approach.
Does HaiPhai Help Implement Prompt Governance?
Yes. HaiPhai's operating partnership and AI Velocity Diagnostic embed senior experts directly into a biotech's operations to design and run governed automation, including the lifecycle stages, verification bands, and control-plane architecture described in this framework.
How Often Should Prompt Governance Programs Be Audited?
Red-band workflows warrant monthly review by the governance board, while lower-risk workflows can follow a quarterly cadence. Align retention and audit frequency with your quality system's existing document-control standards rather than treating AI prompts as a separate schedule.